
See tensors.
Study decks
Every topic on See tensors., organised into decks. Open one to see what it covers, then learn it with flashcards, quizzes and spaced review. Subscribe to a deck to keep it in your study plan and track how well you know it.
22 decks220 topics4 subject areas
Before the workshop
0% complete
Check the linear algebra the workshop builds on, then set up your runtime and meet the nine real datasets.
 Unit 1
Prerequisites - Linear Algebra
Not startedVectors, matrices, norms, eigenvalues, the SVD, the pseudoinverse and PCA: the linear algebra the tensors workshop builds on, from Deep Learning, Ch. 2.
 Unit 2
00 · Setup and Welcome
Not startedThe four words you need before the workshop starts, the nine real datasets it runs on, and the shapes you will meet all day.
Parts I–III · Reading tensors
0% complete
What a tensor is, what every axis counts, and how to index, broadcast, reshape and transpose real data without silent bugs.
 Unit 1
01 · What a Tensor Is
Not startedThe vocabulary the whole workshop runs on — tensor, axis, order, shape, slice, fiber, unfolding, contraction — and the two meanings of “rank”.
 Unit 2
02 · Thinking in N Dimensions
Not startedRead every axis as a question: what does this axis count? Batch against time, the five axis letters, and padding with a validity mask.
 Unit 3
03 · Indexing and Broadcasting Real Data
Not startedSelect by name, not by number. Fancy indexing, Boolean masks, broadcasting — and the zero-variance pixels that make NaN a finding, not a bug.
 Unit 4
04 · Reshape and Transpose Real Images
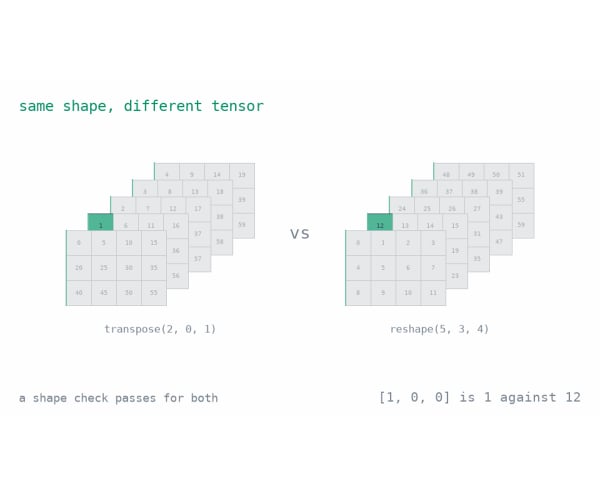
Not startedChanging a tensor’s shape is not the same as moving its axes. HWC, CHW, NHWC, NCHW — and the reshape that runs without error and scrambles the image.
 Unit 5
05 · Video Pipeline Design
Not startedEvery pipeline decision chooses what information is kept, transformed or discarded. Shapes at five stages, sampling loss, and where a camera axis goes.
Part IV · Contract, solve, factorize
0% complete
einsum, the pseudoinverse, recursion, matrix factorizations, Tucker and the tensor factorizations, then the idea that connects them.
 Unit 1
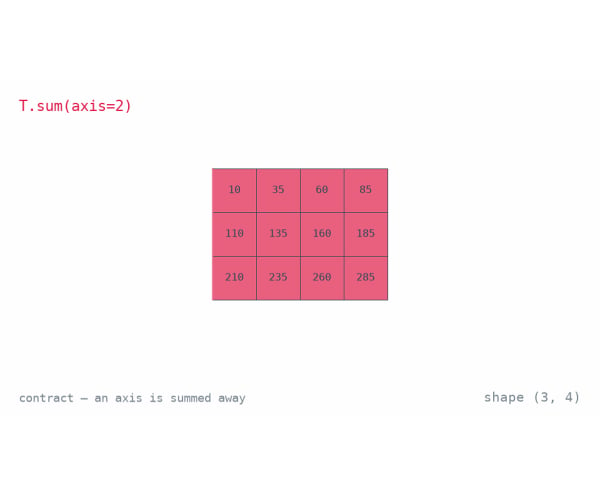
06 · Contraction with einsum
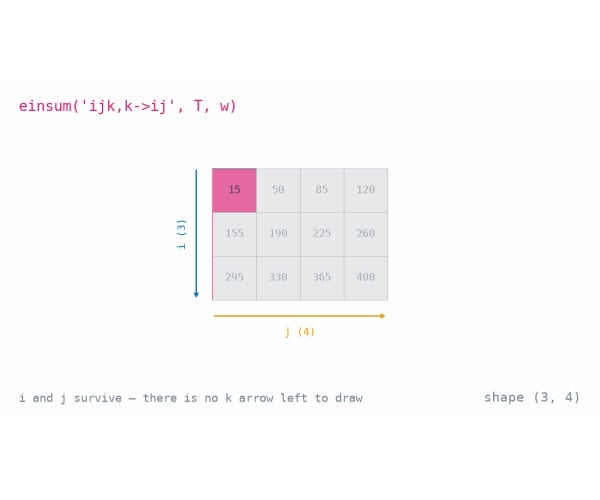
Not startedOne rule: an index that disappears after the arrow is summed over. Grayscale, trace, matrix products and a 1797x1797 similarity matrix, all in one syntax.
 Unit 2
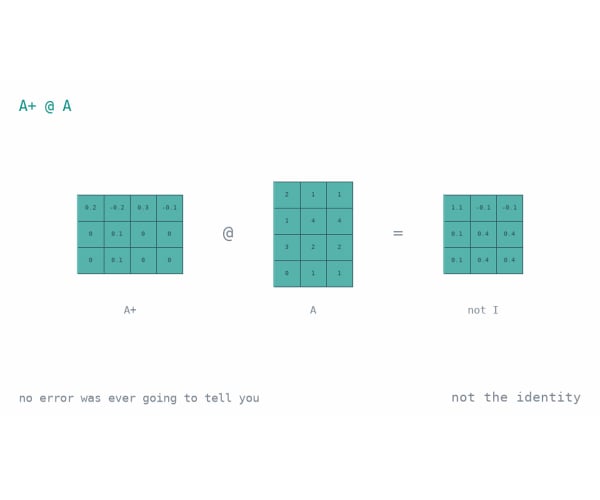
07 · Inverses and the Pseudoinverse
Not startedDoes an exact inverse exist? If not, what useful answer does the pseudoinverse give instead? Solved on 20,433 real California housing districts.
 Unit 3
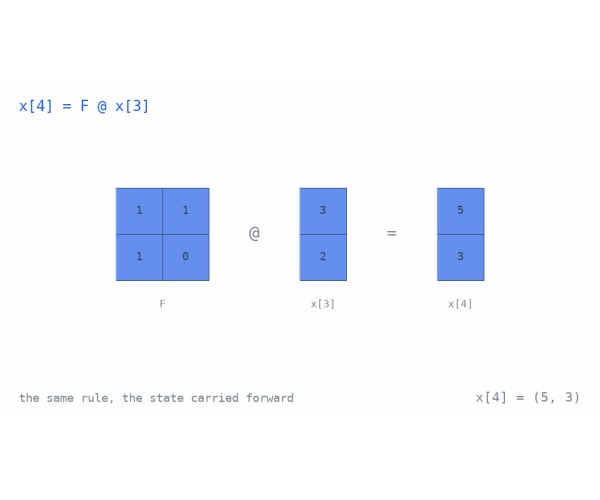
08 · Recursion with Matrices and Vectors
Not startedUse the current state to create the next state, then repeat. Fibonacci, power iteration and a real airline forecast — the structure of a recurrent network.
 Unit 4
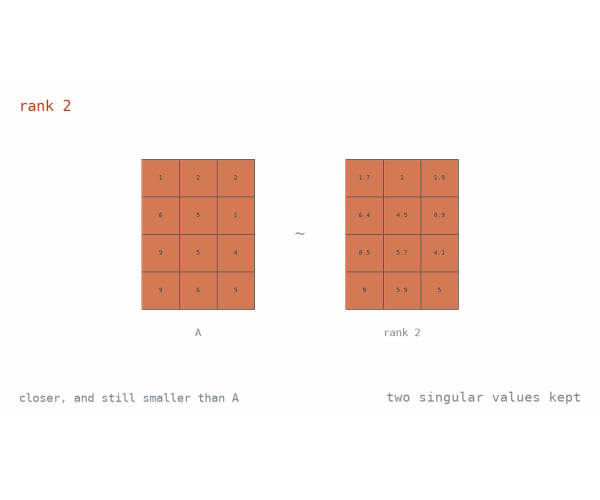
09 · Matrix Factorizations
Not startedWhich factorization do I reach for, and what does it cost? LU, QR, Cholesky, eigendecomposition, SVD and NMF, each asked the same two questions.
 Unit 5
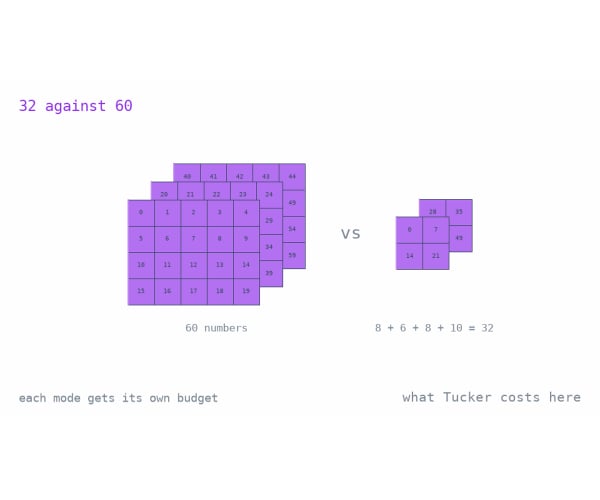
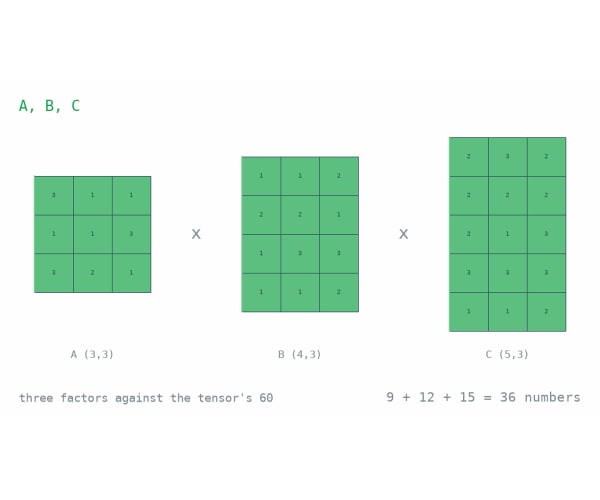
10 · Tucker Decomposition on Real Data
Not startedPCA generalized to every axis. One factor matrix per mode plus a small core — and a real taxi tensor whose hour factor peaks at the evening rush.
 Unit 6
11 · Tensor Factorizations
Not startedCP, Tucker, Tensor Train and t-SVD: four bargains about which structure to keep. Choose the method from the structure, then the rank from the loss.
 Unit 7
12 · Wrap-Up and Take-Homes
Not startedThe idea connecting the workshop, five take-homes (PCA, attention, CP, Cholesky, audio denoising) and the four deep dives opened live.
Deep dives
0% complete
The live labs and take-home deep dives: convolution, CP by hand, generalized CP, PCA from tensors, multi-head attention, feature compression, CP or Tucker in practice, and AlphaTensor.
 Unit 1
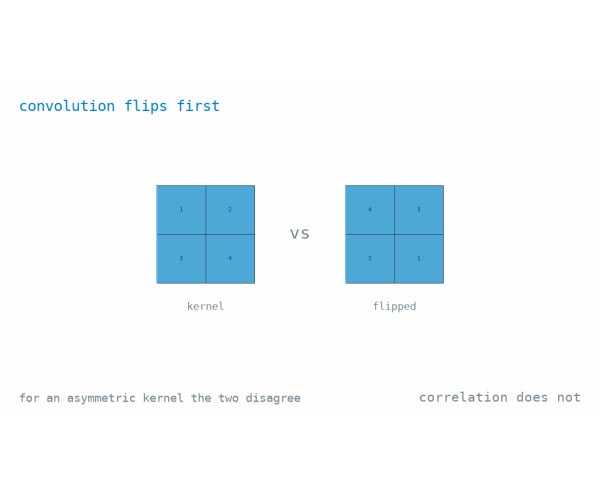
13 · Convolution and Deconvolution
Not startedCorrelation, convolution, transposed convolution, deconvolution: one kernel, four operations, and a real blurred photograph partly recovered.
 Unit 2
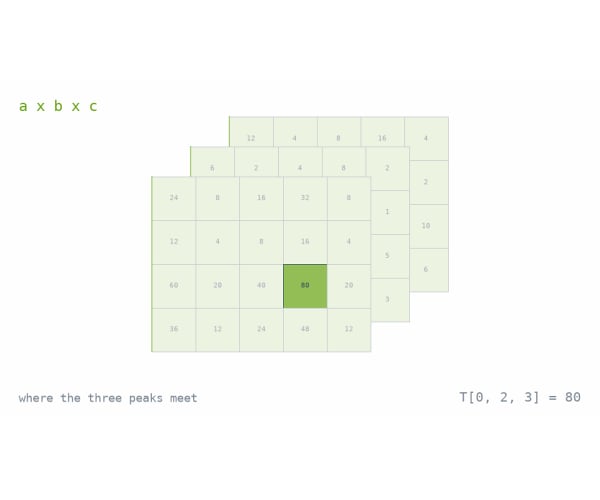
14 · CP Factorization and the Rank-1 View
Not startedA CP component is one vector per axis. Fit it by alternating least squares, keep it non-negative, and watch neural trials sort by a label CP never saw.
 Unit 3
15 · Generalized CP for Counts and Binary Data
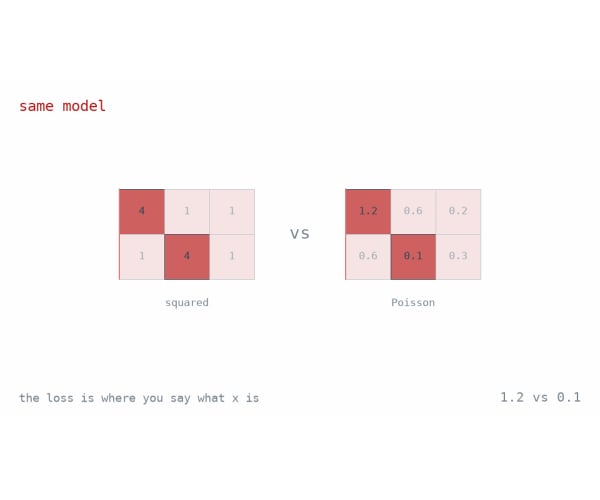
Not startedSquared error is an assumption. Swap in a Poisson or Bernoulli loss, fit real Chicago crime counts, and catch a component that is an artifact of the file.
 Unit 4
16 · PCA from a Tensors Perspective
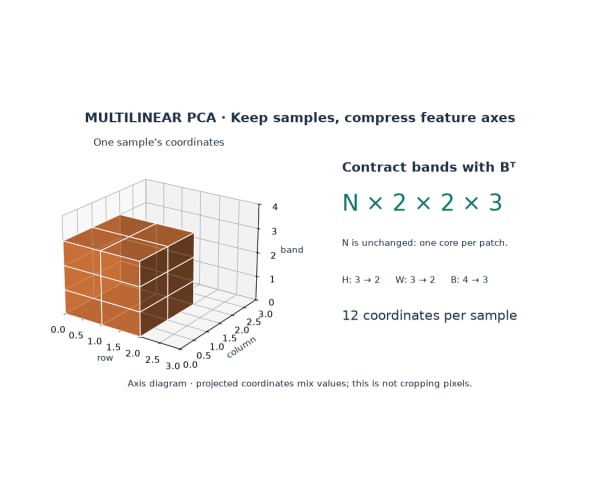
Not startedCovariance, correlation, eigenvectors and SVD on real satellite patches; does PCA help a classifier? Then multilinear PCA and a spiked tensor signal.
 Unit 5
17 · Multi-Head Attention
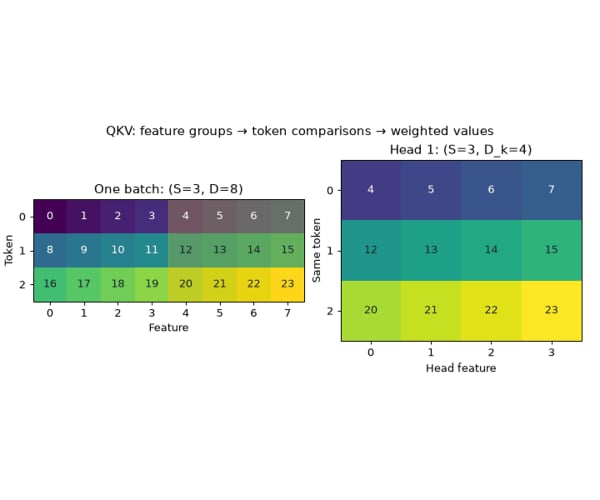
Not startedSplit Q, K and V into heads without losing a token: reshape then transpose, scores over keys, √D_k, merging back, and why shape tests lie.
 Unit 6
18 · Feature Compression
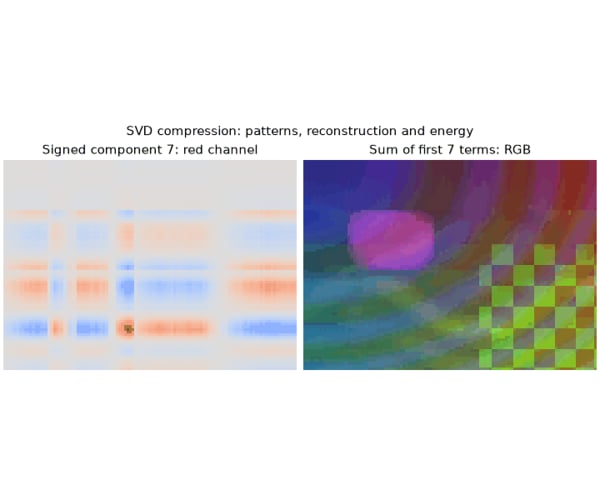
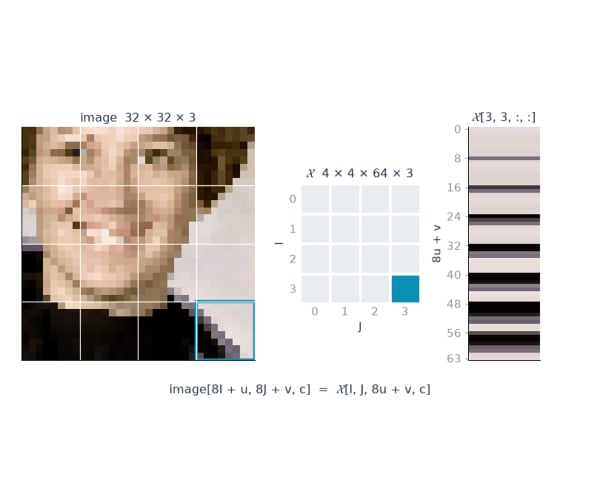
Not startedCompress a feature map by truncated SVD of an unfolding: rank-k reconstruction, energy as squared amplitude, factor storage, and what 95% misses.
 Unit 7
19 · CP or Tucker in Practice
Not startedCP or Tucker? One object separates them, the core. A knowledge graph, a ResNet-18 kernel and a photo show why CP compresses and Tucker predicts.
 Unit 8
20 · AlphaTensor: Multiplying Matrices as a Game
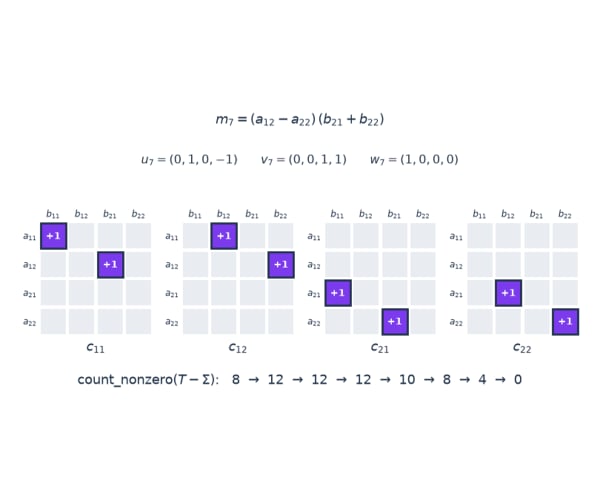
Not startedMatrix multiplication is a tensor of 0s and 1s, and every exact CP split into R terms is an algorithm with R multiplications. Strassen, TensorGame, AlphaTensor.