
17 · Multi-Head Attention
Deep dive 17 of Tensors for Machine Learning. One question about axes:
How do you give every attention head its own axis without losing track of which token is which?
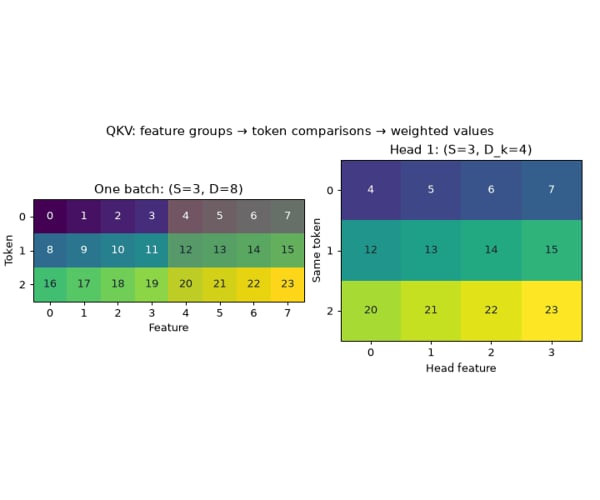
Follow each token from (B, S, D) to (B, H, S, D_k), compute the scores, normalize over the keys, and merge the heads back. It needs exactly two moves you already know: the reshape and transpose of section 04 and the contraction of section 06.
And it has one trap worth the whole lab: a direct reshape gives exactly the right shape and the wrong heads.
In the six-hour workshop this is the first live lab: 25 minutes before lunch, working the core route to “Core complete”. The rest is take-home.
Study here, then run the real thing: notebook 17 on Colab · all notebooks · the attention stage on the interactive page
Built from the workshop’s own material by Ravi Kalia and Sebastian Laverde Chunza, CC BY 4.0.
Your path through this unit
Step 1 of 3
Initial review
Take a first look at each topic and tick Got it once you have the general idea.